A few weeks ago, recording my own voice for speech models was something I did for an hour here and there. Then it became a daily habit, and at some point I lost track of how much there actually is. So I counted.
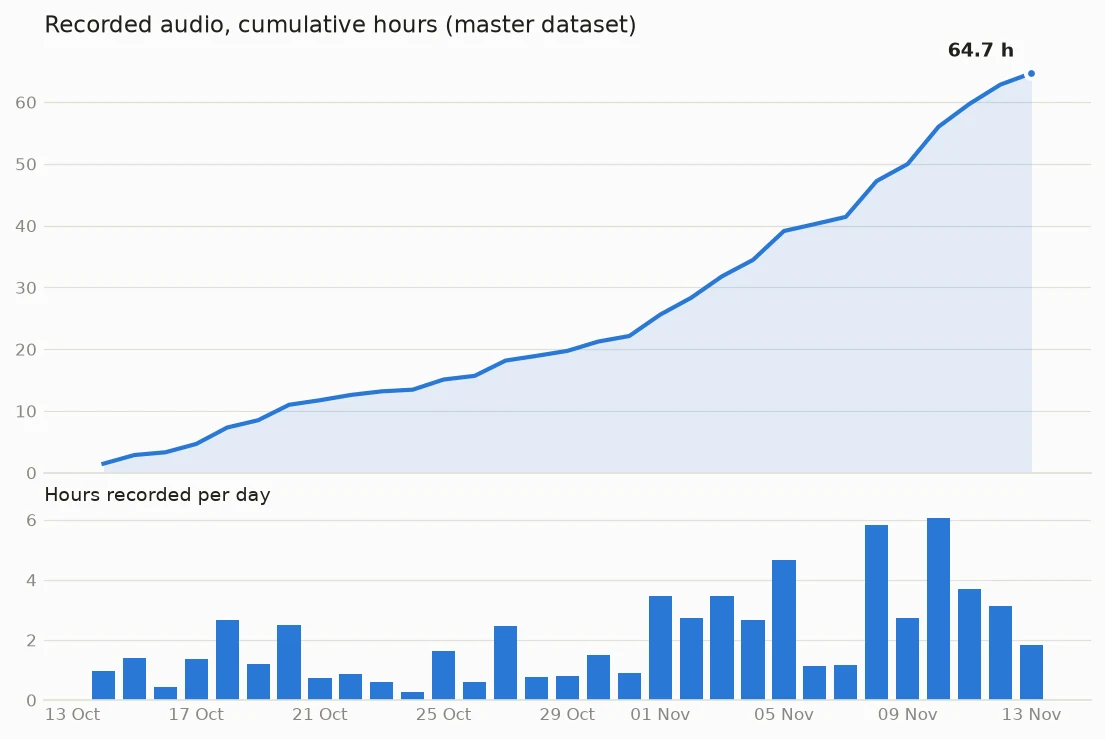
As of today, 13 November 2026, the master dataset holds 64.7 hours of my voice across 46,227 takes. That's the number I'd been loosely calling "about 60 hours", and it turns out I was underselling it. (The growth chart below is a fair picture of what the last month has looked like.)
How the data is organised
Everything starts in one place. Every take I record in the capture app lands in a single master dataset, Read-Aloud-Voice-Sentences on Hugging Face, and every speech model I train draws from it.
Hugging Face Dataset danielrosehill/Read-Aloud-Voice-Sentences ↓ 40.8kAutomatic speech recognitionCC-BY-4.0Updated Nov 2026 View dataset on Hugging FaceThe other datasets are slices of that master, not separate recordings. Tech-Sentences is the takes dense in software and DevOps vocabulary, English-Hebrew-Codeswitching-Sentences is the ones with Hebrew words mixed in, and so on. Some slices have slices of their own (Linux-Admin-Sentences sits inside Tech-Sentences, for instance). Because a take can belong to several subsets at once (a noisy take about Kubernetes is both "noisy" and "tech"), the hours below overlap and don't add up to the total. The 64.7 hours in the master is the real figure.
The biggest slices right now:
Dataset                                  Hours   Takes
Read-Aloud-Voice-Sentences                64.7  46,227
Tech-Sentences                            16.9  10,944
English-Hebrew-Codeswitching-Sentences    15.8   9,489
Noisy-Condition-Sentences                 10.1   7,202
Voice-Command-Sentences                    5.5   7,778
General-English-Sentences                  4.3   3,013
Judaica-Sentences                          2.0   1,034
Israeli-Street-Sentences                   1.6   1,052
Noisy-Condition-Sentences is the odd one out: it groups takes by how they were recorded (in noise, whatever the topic) rather than by what they say.
What it feeds
The same recordings sit underneath every model line:
Sabich, the main Hebrish model, trains on the full mix and is updated as a rolling checkpoint.
Jachnun and Shakshuka (the streaming model) are the code-switching line.
Fritter, my English dictation model for technical vocabulary, trains on the takes without code-switching.
Falafel, the small voice-command model, trains mainly on Voice-Command-Sentences.
Meorav and Fritter-TTS, the text-to-speech voices, use the takes clean enough for speech synthesis.
So when I record a hundred sentences about API work on a Tuesday evening, they end up in several models at once. That's most of the reason I keep everything in one master rather than in separate per-project datasets.
Every audio dataset, by hours
Here is the whole index, largest first. Hours and take counts are as of 13 November 2026, and they will be out of date within a day or two, because I record most days and the datasets sync automatically. For the current numbers, the Audio-Dataset-Index on Hugging Face is rebuilt from the same source.
Hugging Face Dataset danielrosehill/Audio-Dataset-Index Every audio dataset Daniel Rosehill publishes on Hugging Face, on this profile and in the Hebrish organisation (the name of the English-Hebrew speech project), as one tree: which dataset is a superset of which, which… ↓ 58CC-BY-4.0Updated Nov 2026 View dataset on Hugging FaceMost are public. The Hebrew ones, and a few others, are gated (access by request), because there's some potential for misuse with Hebrew speech data specifically.
danielrosehill/Tech-Sentences: 16.9 h, 10,944 takes. Dictation-style English sentences dense in software, DevOps, cloud, self-hosting and AI vocabulary (product….
danielrosehill/English-Hebrew-Codeswitching-Sentences (gated): 15.8 h, 9,489 takes. English sentences with everyday Hebrew words and Israeli names written in Latin letters, read aloud by one….
Hebrish/Noisy-Condition-Sentences (gated): 10.1 h, 7,202 takes. Every take from the main dataset recorded in noise, whatever its category: outdoors, in a noisy room, with….
danielrosehill/Voice-Command-Sentences: 5.5 h, 7,778 takes. One speaker reading desktop voice commands for a KDE Plasma voice-command agent: launching, switching to and….
danielrosehill/General-English-Sentences: 4.3 h, 3,013 takes. Plain, everyday English sentences (emails, messages, general prose and homophone pairs) read aloud by one….
Hebrish/Jewish-Religious-Terminology-Sentences (gated): 4.2 h, 2,373 takes. English sentences with Jewish religious vocabulary written in Latin letters: Shabbat and the festivals,….
Hebrish/Judaica-Sentences: 2.0 h, 1,034 takes. Real sentences from traditional Jewish works in English, read by one speaker, Hebrew terms in romanized form:….
Hebrish/Israeli-Street-Sentences: 1.6 h, 1,052 takes. Everyday English sentences naming one Israeli street each (addresses, directions, errands), read by one….
danielrosehill/Linux-Admin-Sentences: 0.9 h, 551 takes. Dictation-style English sentences about Linux desktop and server administration (KDE Plasma, GNOME, systemd,….
danielrosehill/AI-Interactions-Sentences: 0.8 h, 618 takes. Instructions dictated to AI coding agents (Claude Code, Codex and others) and the git and GitHub workflow….
Hebrish/Tanach-Verse-Sentences: 0.7 h, 347 takes. Real Tanakh verses in English, Metsudah translation via Sefaria (sefaria.org), licence CC-BY, read by one….
danielrosehill/Personal-Vocabulary-Sentences: 0.7 h, 532 takes. English sentences built around names a speech model gets wrong for one speaker: his own name, his company and….
Hebrish/Brand-Name-Sentences (gated): 0.7 h, 382 takes. Natural sentences with company, product, AI model and open-source project names (Anthropic, OpenRouter,….
Hebrish/Claude-Dictations: 0.7 h, 137 takes. One speaker reading his own prompts to an AI coding agent (Claude Code): requests, project directions,….
Hebrish/Date-Time-Sentences: 0.6 h, 542 takes. Dates and times said the way people say them and written the way they are typed in an email or a document,….
Hebrish/Yiddish-Sentences (gated): 0.6 h, 353 takes. English sentences with Yiddish words written in Latin letters (shul, daven, cholent, mensch, freier,….
Hebrish/AI-Integration-Sentences: 0.5 h, 329 takes. English sentences naming one item each: apps and services used with an AI assistant: ChatGPT apps, Claude….
Hebrish/Numerics-Sentences: 0.5 h, 472 takes. Every kind of number that is not money, said by one speaker in a fixed way and written the way it is typed:….
Hebrish/Whispered-Sentences: 0.5 h, 312 takes. Experimental robustness data.
Hebrish/Open-Source-Sentences: 0.5 h, 306 takes. English sentences naming one item each: the biggest open-source and self-hosted projects (awesome-selfhosted,….
Hebrish/Irish-English-Sentences (gated): 0.5 h, 326 takes. Everyday sentences in Irish English read by one speaker born in Ireland: vocabulary (craic, grand, giving….
Hebrish/AI-Model-Sentences: 0.5 h, 279 takes. English sentences naming one current AI model each (GPT-6.1 Terra, Claude Opus 5.5, Qwen3.8 Max, Kimi K3.1….
danielrosehill/Smart-Home-Sentences: 0.4 h, 269 takes. Dictation-style English sentences about home automation (Home Assistant, Zigbee, Z-Wave, Matter, Thread,….
Hebrish/Email-Address-Sentences: 0.4 h, 242 takes. One speaker saying email addresses aloud inside everyday sentences: role addresses (support, billing,….
Hebrish/Web-Address-Sentences: 0.4 h, 250 takes. One speaker saying web addresses aloud ("hebrish dot app slash benchmarks", "h t t p s colon slash slash",….
Hebrish/GitHub-Trending-Sentences: 0.3 h, 188 takes. English sentences naming one item each: open-source projects trending on GitHub, probed periodically, read by….
Hebrish/Israeli-Name-Sentences (gated): 0.3 h, 209 takes. English messages and emails that mention an Israeli or Jewish person's name, a first name (Naftali, Yotam,….
Hebrish/Dev-Stack-Sentences: 0.3 h, 170 takes. English sentences naming one item each: libraries, frameworks, CLIs and services from Daniel's own….
Hebrish/Pronunciation-Variants (gated): 0.3 h, 186 takes. Takes in which a word was deliberately said one particular way, from the main dataset, stratified by….
Hebrish/Currency-Sentences (gated): 0.3 h, 173 takes. One speaker saying amounts of money the natural way ("50 shekels", "a dollar fifty", "6 pounds 50").
danielrosehill/Homophone-Context-Sentences: 0.2 h, 158 takes. English sentences whose context settles which spelling of a homophone is meant (their/there,….
Hebrish/Israeli-Place-Sentences: 0.2 h, 165 takes. Everyday English sentences naming one Israeli place each, read by one speaker: second-tier towns, kibbutzim,….
Hebrish/Disfluent-Read-Sentences (gated): 0.2 h, 55 takes. Experimental.
Hebrish/Phone-Number-Sentences: 0.2 h, 112 takes. One speaker dictating phone numbers inside everyday sentences, read digit by digit (oh or zero), with double….
Hebrish/Israeli-Business-Sentences: 0.2 h, 132 takes. Everyday English sentences naming Israeli businesses read by one speaker: banks and insurers, supermarket and….
Hebrish/Idiom-Sentences: 0.2 h, 122 takes. Natural sentences with English idioms that speech recognition tends to spell as a sound-alike ("free rein",….
Hebrish/Procurement-Sentences: 0.2 h, 108 takes. Business sentences with purchasing and trade vocabulary read by one speaker: Incoterms 2020 (EXW, FCA, FOB,….
Hebrish/Entity-Dense-Sentences: 0.2 h, 63 takes. One speaker reading sentences that pack three or more entities into one line: company and product names,….
Hebrish/Colloquial-Reduction-Sentences: 0.1 h, 127 takes. One speaker reading everyday messages with reduced spoken forms (gonna, wanna, gotta, kinda, sorta, 'cause /….
Hebrish/Data-Tool-Sentences: 0.1 h, 79 takes. English sentences naming one item each: news data sources and APIs (GDELT and others), scraping frameworks,….
Hebrish/Acronym-Sentences: 0.1 h, 99 takes. Natural sentences with acronyms read by one speaker, both spelled out (API, SSH, HTTPS) and said as words….
Hebrish/Shingle-Sentences: 0.1 h, 98 takes. English sentences on independent professional practice, read by one speaker: roles in AI and technical work,….
Hebrish/API-Ops-Sentences: 0.1 h, 102 takes. English sentences about API work, read by one speaker: HTTP methods in capitals (GET, POST, PUT, PATCH,….
Hebrish/NATO-Alphabet-Sentences: 0.1 h, 70 takes. Experimental.
Hebrish/Architecture-Practice-Sentences: 6 min, 73 takes. English sentences of professional architecture vocabulary, read by one speaker: reality capture (LiDAR,….
Hebrish/Long-Tech-Sentences: 6 min, 11 takes. One speaker reading dictation-length tech passages, about 25 to 55 seconds in one take.
Hebrish/Functional-GI-Sentences: 5 min, 67 takes. English sentences of functional gastrointestinal vocabulary, read by one speaker describing his own symptoms,….
Hebrish/Hard-ASR-Sentences (gated): 5 min, 79 takes. English sentences speech recognition finds hard, read by one speaker: Harvard sentences (IEEE 1969, public….
Hebrish/Latin-Phrase-Sentences: 5 min, 58 takes. One speaker reading English sentences that use a Latin phrase (de facto, ad hominem, de minimis, bona fide,….
Hebrish/Israeli-TV-Sentences: 5 min, 56 takes. Everyday English sentences naming one Israeli TV show each, read by one speaker: long-running satire,….
Hebrish/Hardware-Sentences: 5 min, 64 takes. Short workshop and DIY sentences with hardware vocabulary read by one speaker: electronic components….
Hebrish/Expanded-Acronym-Sentences (gated): 4 min, 52 takes. Chat and business shorthand said as letters by one speaker ("by E O D", "F Y I", "I M O") with the transcript….
Hebrish/Spelled-Out-Sentences: 4 min, 55 takes. One speaker spelling names, words and codes letter by letter in dictation ("my surname is B R E N N A N"),….
Hebrish/Repeated-Word-Sentences (gated): 4 min, 19 takes. Experimental.
Hebrish/Fragment-Sentences: 3 min, 80 takes. One speaker reading short and incomplete utterances, one to six words: message replies ("Not yet."), single….
Hebrish/Long-Code-Switching-Sentences: 3 min, 7 takes. One speaker reading dictation-length English passages with romanized Hebrew, about 25 to 55 seconds in one….
Hebrish/Self-Correction-Sentences: 3 min, 27 takes. One speaker correcting himself mid-sentence ("send it Tuesday, no, Wednesday").
Hebrish/Fast-Speech-Sentences: 1 min, 34 takes. Robustness data.
Hebrish/Singing-Sentences: 1 min, 16 takes. Experimental.
Hebrish/Background-Speech: 1 min, 12 takes. Every take from the main dataset with another voice audible behind the speaker: someone talking in the room,….
Hebrish/Thinking-Pause-Sentences: 1 min, 8 takes. Everyday English sentences read by one speaker with a deliberate thinking pause (a second or two of silence)….
Hebrish/Spoken-Aside-Sentences: 1 min, 5 takes. One speaker dictating a sentence and, partway through, saying something to someone in the room ("come in,….
Hebrish/Paragraph-Dictation-Passages: 1 min, 3 takes. Experimental.
Hebrish/Weird-Voice-Sentences: 1 min, 6 takes. Experimental.
Hebrish/False-Start-Sentences: 1 min, 6 takes. Experimental.
Outside the master
A few audio datasets aren't slices of the master: earlier recordings from before the capture app existed, contributions from other people, and experiments.
Hebrish/Hebrish-TTS-Voice-Recordings (gated): takes clean enough to train the text-to-speech voices (Meorav and Fritter-TTS).
Hebrish/English-Hebrew-Mixed-Sentences (gated): The first code-switching set: sentences with recordings (637 WAV files, checked 2026-11-05).
Hebrish/Community-Voice-Contributions: Recordings contributed by anyone, for the speech models.
Hebrish/Synthetic-Codeswitching-Voices-Pilot: 100 synthetic clips (2026-10-28): English sentences with one Hebrew term.
danielrosehill/Tech-Sentences-For-ASR-Training: Early tech sentences with audio; a prompt source for the bank.
danielrosehill/Wake-Words: Wake-word recordings.
What's next
The obvious gap is that almost all of this is one speaker: me. The models need other voices (different accents, genders and communities) far more than they need another ten hours of mine. If you'd like to contribute recordings, the Hebrish site has a page for it.
In the meantime, I'll keep recording a few hours a week and rebuilding the index.
