This is an idea in development, not a release. I'm writing it up now because the plan is clear enough to explain, and because I'd like to hear from anyone who has tried something similar.
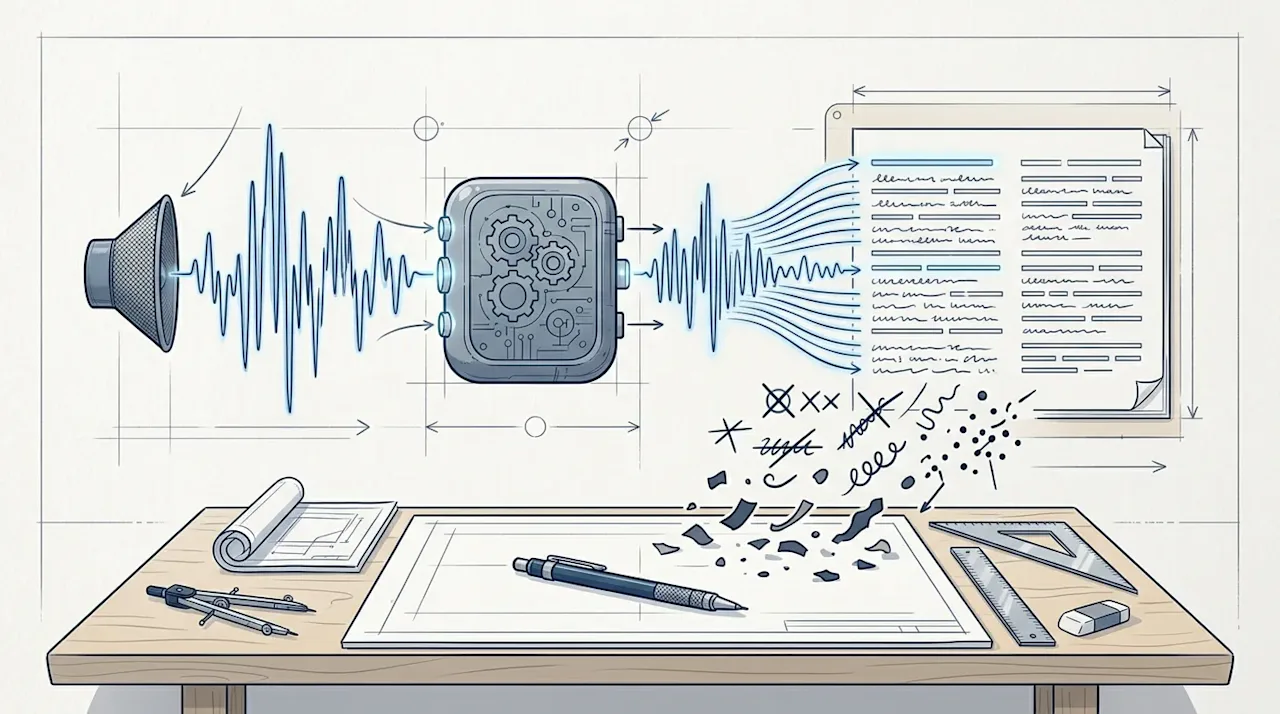
Every dictation setup I use works in two steps. A speech recognition model writes down what I said, and then something else (usually an LLM) cleans it up: it removes the "ums", fixes the false starts, writes "two thousand shekels" as 2,000 NIS, and splits the wall of text into paragraphs. The second step is where the cost, the latency and the occasional weird rewrite come from. So I keep asking myself: what if the speech model just did the cleanup itself?
That is Proofed. The idea is a stock ASR model (NVIDIA Parakeet TDT 0.6B v2 to start) fine-tuned only on post-processing tasks, so the transcript comes out already proofed. One small model, one pass, no LLM afterwards.
GitHub Repository danielrosehill/Proofed Proofed: integrated ASR + post-processing model, from speech straight to clean, proofed text. Updated Oct 2026 View on GitHubWhat "proofed" means here
The project keeps this deliberately separate from vocabulary. Teaching a model new words is a different problem, and my Hebrish and Fritter models already deal with it. Proofed isolates the post-processing tasks:
dropping fillers, repeated words and false starts
applying self-corrections ("Tuesday, no, Wednesday" becomes "Wednesday")
leaving out remarks to someone else in the room
numbers, money and dates as digits
paragraph breaks
handling whispered speech
Is it feasible?
The first phase was a research pass, done on 24 October and written up in the repo, and it came back as viable. A few of the findings shaped the plan:
Parakeet has no newline token. Its tokenizer turns
\ninto a space, and none of the 22 Parakeet, Canary and Nemotron models I checked has one. The plan is to add a newline token to the vocabulary, the way NVIDIA added an end-of-utterance token to one of its streaming models.No ASR model I could find writes paragraphs natively. The commercial APIs that offer paragraphs add them after recognition.
End-to-end disfluency removal has been done, on Switchboard and more recently with Whisper, but nothing covers dictation-style self-corrections, asides or paragraphs, and nothing used a transducer model like Parakeet.
Where it stands
There's no model yet. The training data has a first snapshot of about 75 minutes of my own takes, each paired with the clean text I want back, and I'm still recording towards per-task targets. The research pass found none of my existing takes had a self-correction in them, so self-corrections, asides and numbers will partly be synthesised.
Hugging Face Dataset danielrosehill/Proofed-ASR-Cleanup-Training-Data Audio paired with clean, proofed target text for training an ASR model to do its own post-processing: no fillers, repeats or false starts, numbers and money as digits, self-corrections applied, asides to other people… ↓ 99Automatic speech recognitionCC-BY-4.0Updated Oct 2026 View dataset on Hugging FaceMeanwhile, I trained the two-step version properly. S1-ASR-Cleanup is a small text model that does the cleanup half on its own, and it doubles as the baseline Proofed has to beat. If a 0.6B speech model can match it with no second step, the idea works. If not, I'll have learned something about where this kind of cleanup belongs.
Hugging Face Model danielrosehill/S1-ASR-Cleanup S1-ASR-Cleanup is a fine-tune of S1-mini by Superwhisper (superwhisper/s1-mini, Qwen3-0.6B) that cleans raw speech-to-text dictation the way one user edits his own. One standalone model: the LoRA is merged in, nothing… ↓ 358Text generationUpdated Oct 2026 View model on Hugging FaceThe project brief, the research report and the task taxonomy are all public in the repo.
