Version 3 of my English-Hebrew code-switching fine-tune of NVIDIA's Parakeet TDT 0.6B v2 is out on Hugging Face: Parakeet-TDT-0.6B-v2-English-Hebrew-Codeswitching. It transcribes English speech with Hebrew words mixed in, the way English speakers in Israel actually talk, and writes each Hebrew word in one consistent Latin spelling. v3 was trained on 196 minutes of code-switched speech, up from 120 minutes in v2.
Hugging Face Model danielrosehill/Parakeet-TDT-0.6B-v2-English-Hebrew-Codeswitching ↓ 2.2kAutomatic speech recognitionCC-BY-4.0Updated Oct 2026 View model on Hugging FaceUpdate (19 October 2026): the project now has a website, hebrish.app, where you can get the Hebrish keyboard for Android and the desktop apps and find every model, dataset and demo in one place.
Results
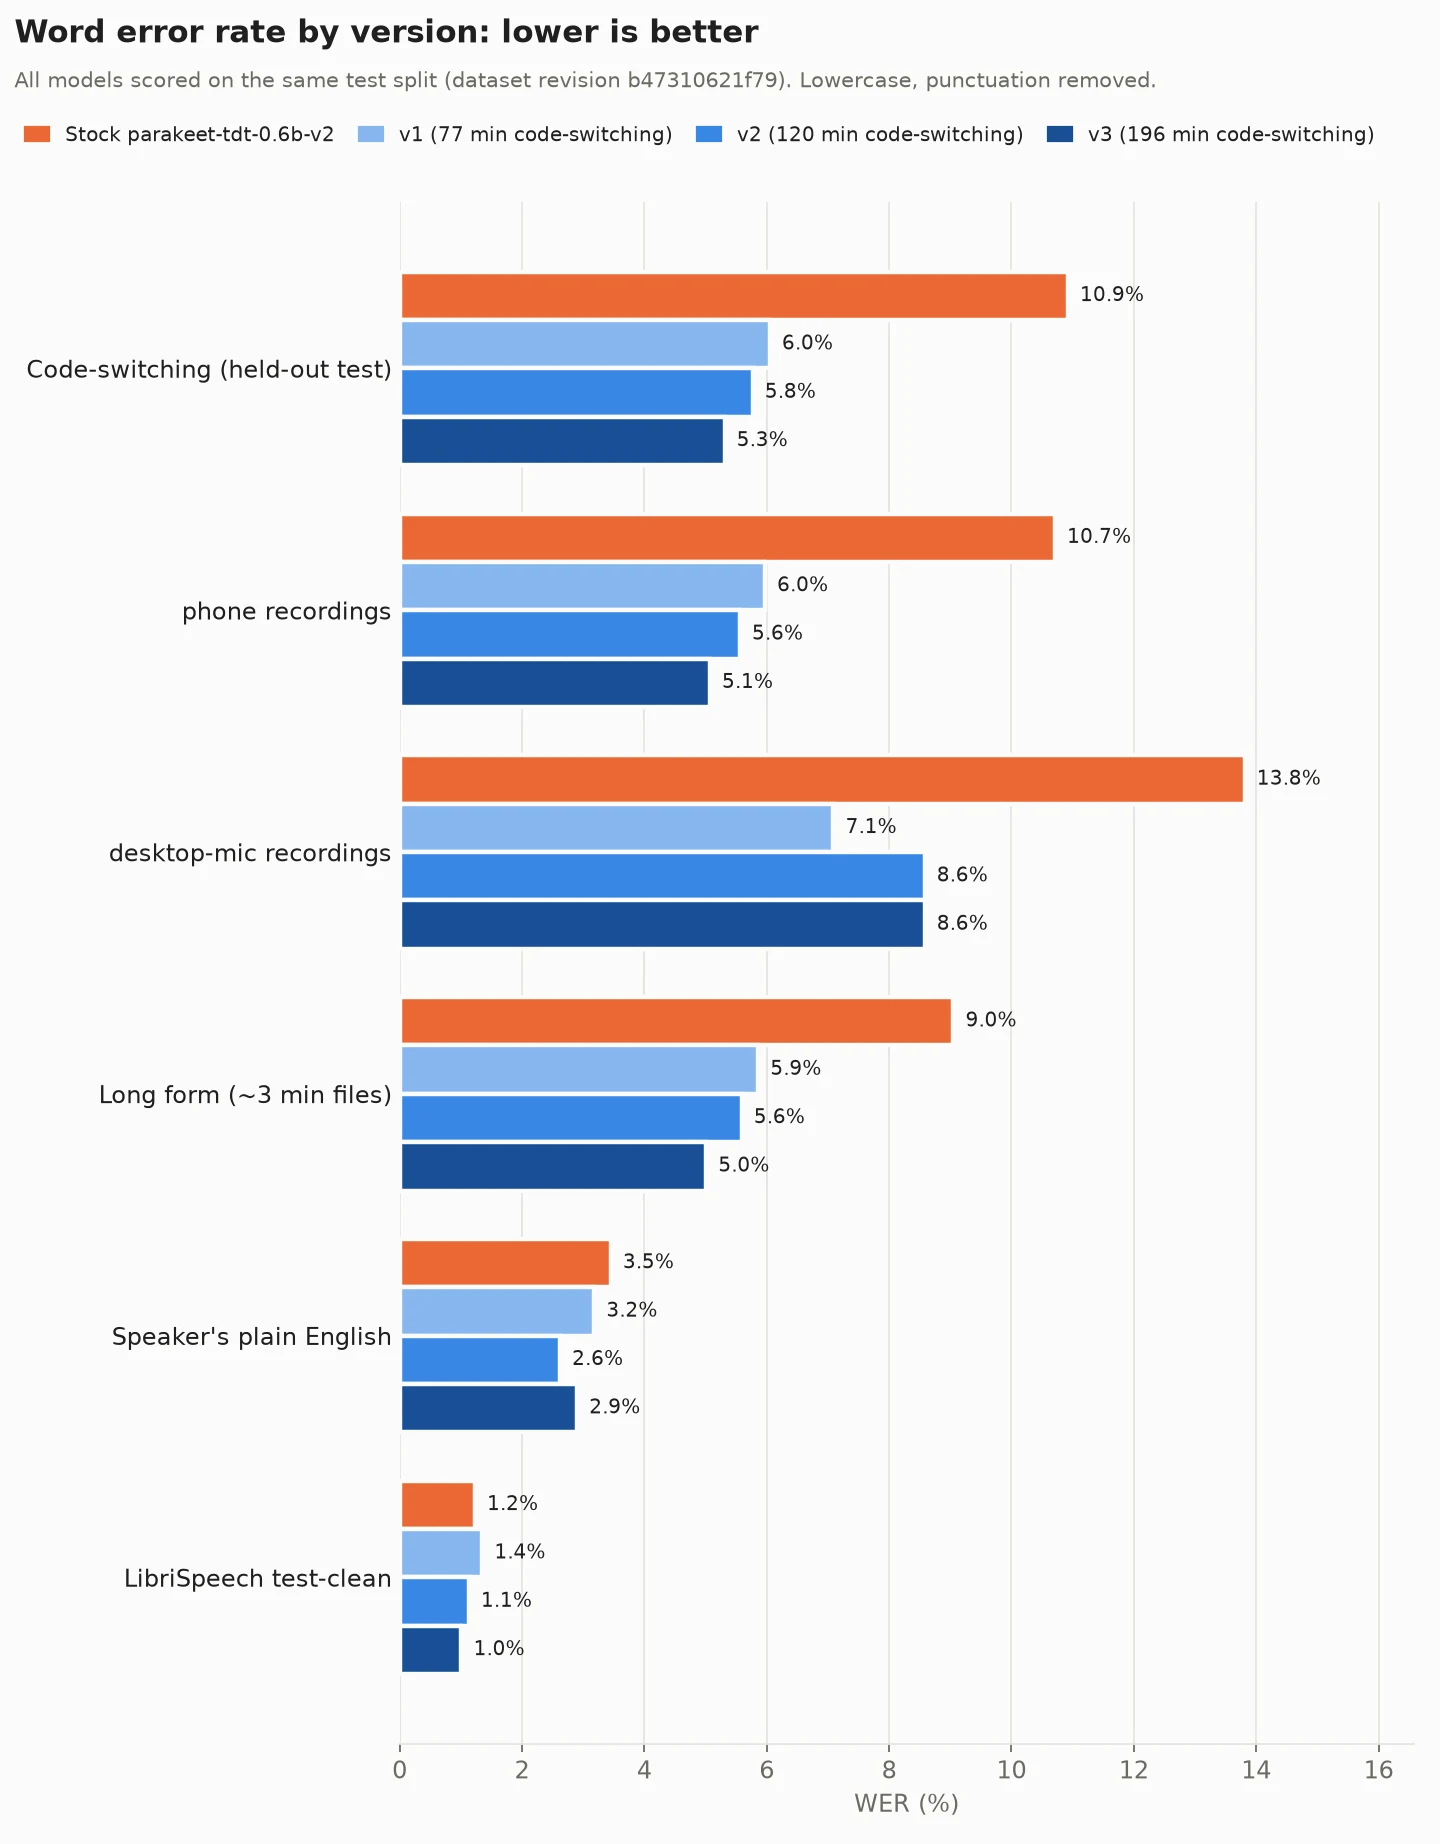
Scored on a held-out test split of 219 code-switched clips. The split is term-disjoint: some Hebrew terms never appear in training, so the "never seen" figure measures generalisation rather than memorisation. Stock Parakeet v2 versus v3:
Code-switching word error rate: 10.9% → 5.3%
Hebrew terms seen in training, transcribed correctly: 29% → 66%
Hebrew terms never seen in training, transcribed correctly: 27% → 48%
Long-form dictation WER (~3-minute files): 9.0% → 5.0%
Plain English, my own voice: 3.5% → 2.9%. LibriSpeech test-clean: 1.2% → 1.0%
Code-switching errors are roughly halved, and English accuracy did not get worse.
Every version on the same test
The test split grew from 121 to 219 clips for this release, so the v2 numbers published earlier are not comparable. Stock Parakeet and all three versions were re-scored on the new split:
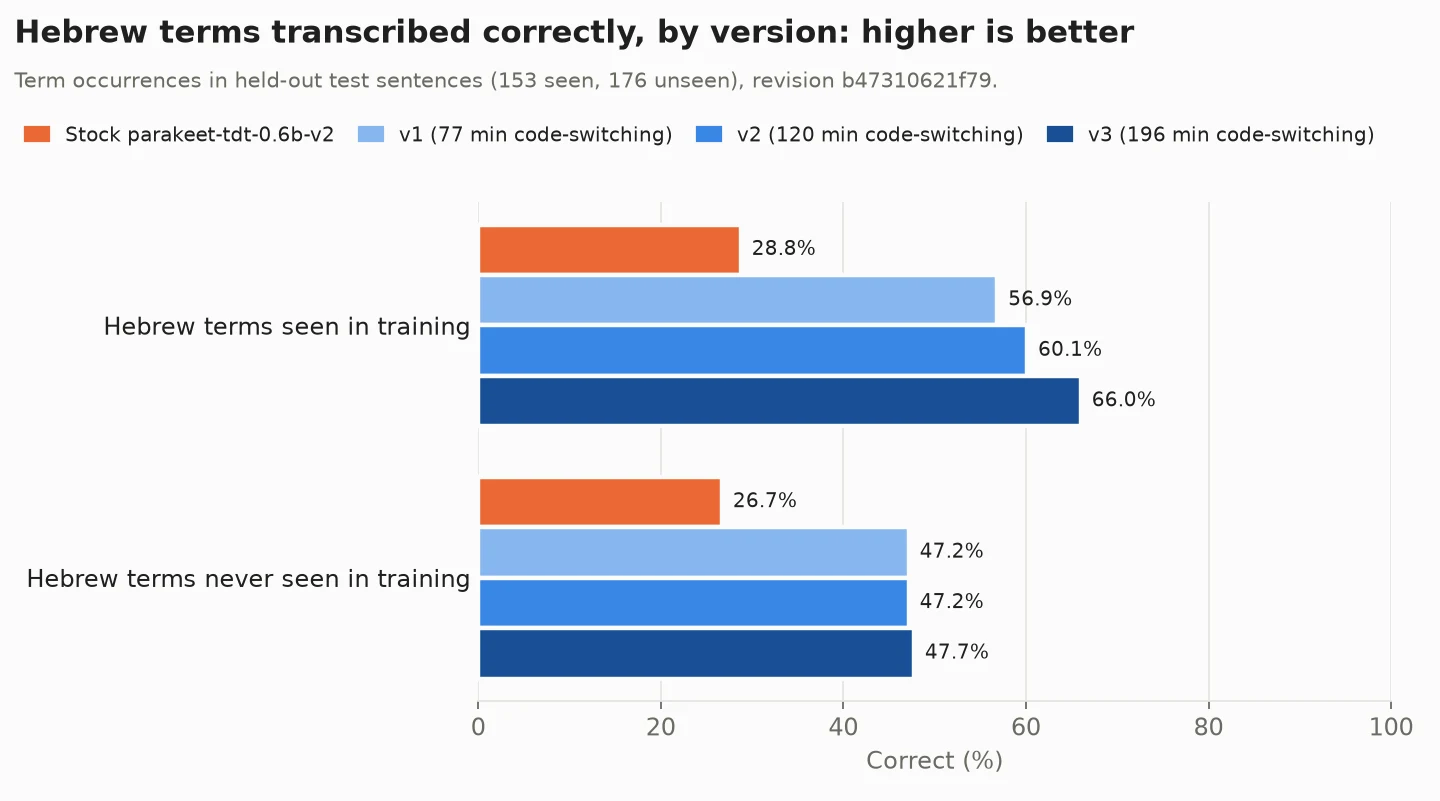
The main finding across three versions: the big jump on unseen words came in v1, when the model learned how my Hebrew pronunciation maps to romanised spelling. Since then, more audio improves the words it has recordings of (60% → 66% from v2 to v3) but barely moves the words it has never heard (47% → 48%). So recording is now targeted at the terms stock Parakeet never gets right, rather than at more minutes.
Get it
Model, with GGUF for Android dictation, ONNX and NeMo: Hugging Face
On Android, as a voice keyboard: my Codeswitch Voice APK (proof of concept, v0.1.0). It downloads the v3 weights once and runs fully on the phone, behind HeliBoard's mic key.
Dictate with it on your phone: an Android voice keyboard that runs v3 on-device (test build, Android 9+, arm64): download the APK (source)
Try it side by side with stock Parakeet: demo Space
Full write-up of v3, with training details: English-Hebrew Code-Switching Parakeet: Version 3
Project tracker: GitHub
Next is v4 at 270 minutes, comparing how much plain English the training mix needs. Recordings from other English speakers in Israel would help most. If you can contribute, get in touch.
