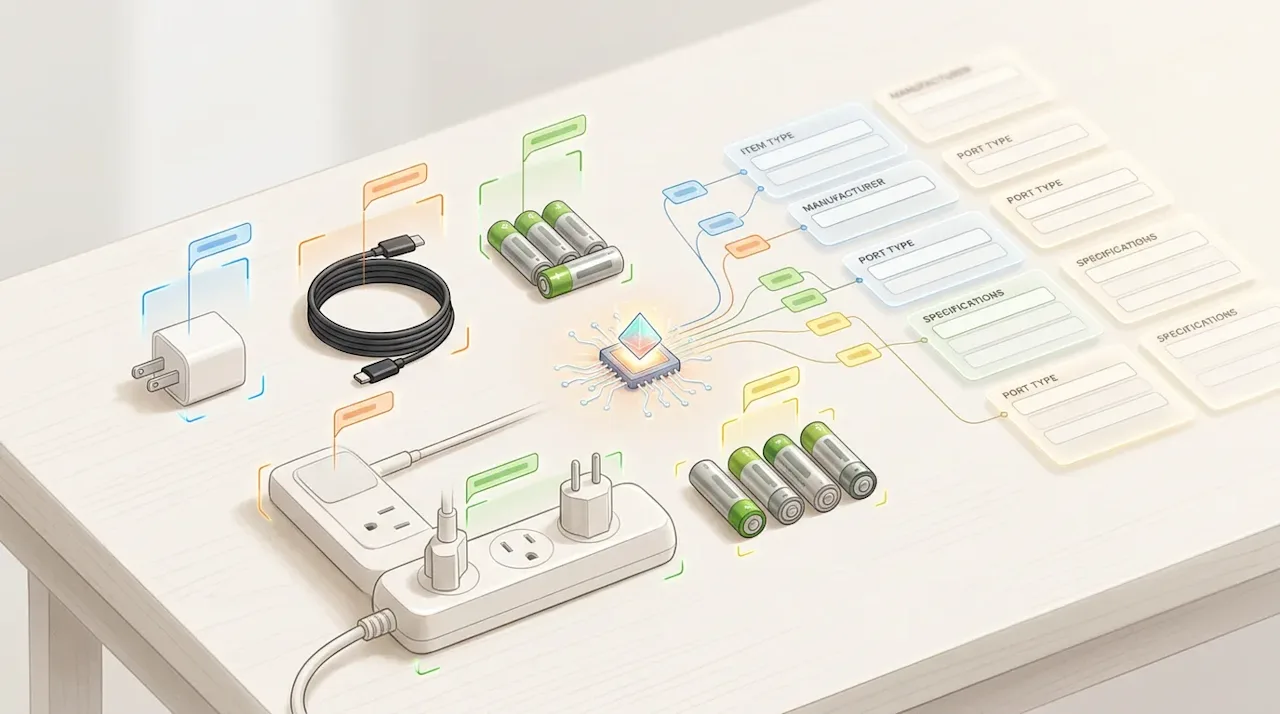
inventory-spec-extractor is a small model for my home inventory. Give it one line of a free-text product specification and it marks the attributes in it:
Hugging Face Model danielrosehill/inventory-spec-extractor A small model (33M parameters, int8 ONNX, about 34 MB) that finds structured attributes in one line of a free-text product specification: Token classificationAPACHE-2.0Updated Oct 2026 View model on Hugging FaceOutput: 12V 3A→12Voutput_voltage,3Aoutput_currentLength: 2m, USB-C to USB-A→2mcable_length,USB-CandUSB-AconnectorPlug: Israeli (Type H), Power: 2200W→Type Hplug_type,2200Wpower
It knows 25 attributes, including manufacturer, model number, input and output voltage and current, battery type, connector, plug type, cable length, material, colour and IP rating. It only finds and labels spans. Unit conversion and normalising spellings are left to ordinary code, which does that job better.
Why a model and not regex
Regex handles 12V fine. It falls apart on materials, connectors and power sources, where the same attribute is written a dozen different ways. On the validation split of inventory-spec-lines (1,477 lines, split by item):
Regex baseline: F1 0.58 (precision 0.80, recall 0.45)
This model: F1 0.85 (precision 0.83, recall 0.86)
The biggest gains are on materials (0.54 → 0.93), connectors (0.36 → 0.84) and power sources (0.00 → 0.78). One caveat: the evaluation labels are silver (labelled by Claude Haiku 5.5, not checked by hand), so these numbers measure agreement with that teacher.
Known weaknesses
Currents are the weak spot. On a line like "Power: 12V, 3A, 36W" it can label the amp value as power, and output current scores below the regex baseline. A unit check in the calling code catches that (an amp value is never a power). Versions and part numbers had too few training examples to be reliable.
Under the hood
It's a fine-tune of BAAI/bge-small-en-v1.5 (33M parameters), trained for six epochs on a Modal T4 and exported to int8 ONNX. The download is about 34 MB, and it runs on CPU, in the browser or on a small server through onnxruntime-web, at about 20 ms per line. The training data, with personal serial numbers removed, is public as inventory-spec-lines.
It's one piece of moving my flat onto industrial storage standards: an inventory is only useful if the specs in it can be searched.
